Read the benchmark report
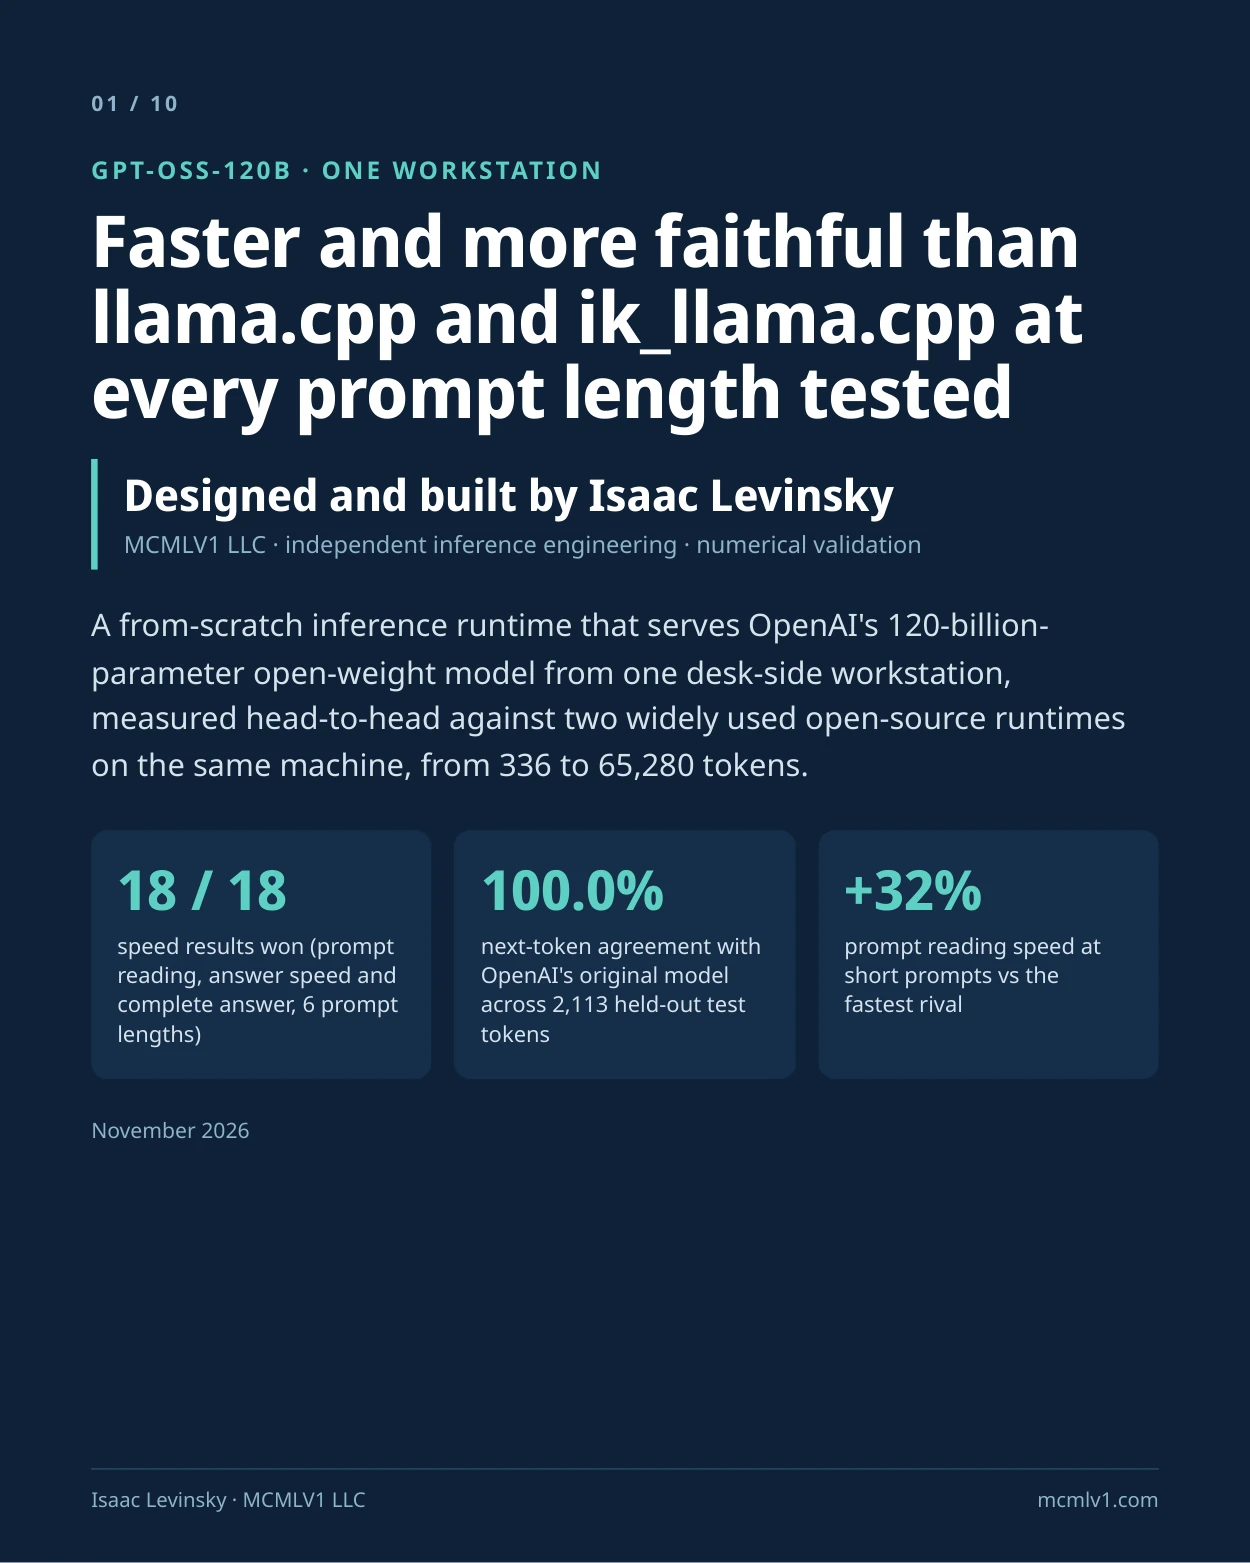
Browse all ten pages below or download the original public PDF. The graphs cover prompt processing, answer generation, end-to-end latency, ongoing conversations, fidelity, and measurement method. The results are specific to the tested workstation and configurations.
What was measured
Hardware-aware execution
A roughly 65 GB 117B-parameter MoE checkpoint across two generations of NVIDIA GPUs (24 GB combined VRAM), CPU compute, and system RAM.
Fair comparison
Source-built competitors with tuned settings, identical prompt tokens, 256-token greedy-decoded answers, and one request at a time.
Numerical fidelity
The custom runtime matched the original model's selected next token across 2,113 tested answer tokens. This is model fidelity, not a claim that model answers are always factually correct.
Scope of result
Measured on this one workstation from 336 to 65,280 prompt tokens. The public PDF discloses run counts; broader hardware claims would require separate benchmarking.
Engineering discussions
MCMLV1 works on inference runtimes, GPU kernels, numerical verification, memory movement, and private AI deployment. For a technical briefing or a conversation about paid engineering work, contact MCMLV1. Detailed benchmark records and technical method can be discussed under an appropriate NDA.